I am a second-year Ph.D. student in Computer Science at Stony Brook University, advised by Paola Cascante-Bonilla. My research uses multimodal data (language / images / video / depth / audio / tactile signals) to advance spatial reasoning, develop intelligent multimodal models, and build generalizable embodied systems, drawing on agentic systems, foundation models (world models and multimodal action models), and reinforcement learning for challenging manipulation tasks (contact-rich / dynamic / long-horizon / deformable), whole-body control, and loco-manipulation. I spent last summer as a Research Scientist Intern at Mitsubishi Electric Research Laboratories, working on dynamic manipulation, visuotactile world-action models, and humanoid loco-manipulation. Previously, I completed my M.Sc. in Computer Vision at MBZUAI, where I worked on generalization in robotic manipulation and embodied agent systems under Ivan Laptev’s supervision. There, I developed embodied agents that observe their environment, reason, plan, act, and recover from failures to complete complex manipulation tasks and support zero-shot sim2real transfer. During my undergraduate studies, I worked with Ognjen Arandjelović on data-efficient learning, developing a minimum description length criterion for SVM hyperparameter selection.
Rocktim Jyoti Das*, Harsh Singh*, Diana Turmakhan, Muhammad Abdullah Sohail, Mingfei Han, Preslav Nakov, Fabio Pizzati, Ivan Laptev
Under Review
Trains compact language-model agents on automatically generated demonstrations from MALMM’s single-agent setup, enabling manipulation on unseen tasks and real robots.
Shijian Deng, Kai Wang, Tianyu Yang, Harsh Singh, Yapeng Tian
EMNLP, 2025
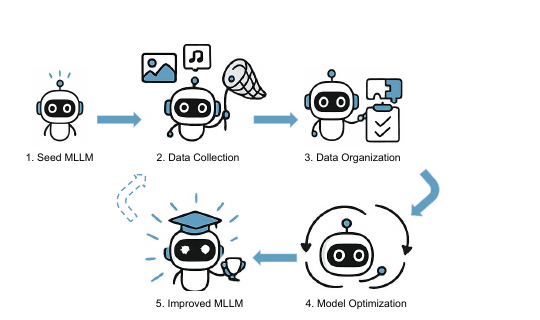
Surveys how multimodal models improve through data generation, curation, and training, covering supervised fine-tuning, reinforcement learning, and preference optimization.
Shijian Deng, Erin E. Kosloski, Siddhi Patel, Zeke A. Barnett, Yiyang Nan, Alexander Kaplan, Sisira Aarukapalli, William T. Doan, Matthew Wang, Harsh Singh, Pamela R. Rollins, Yapeng Tian
IEEE TMM, 2025
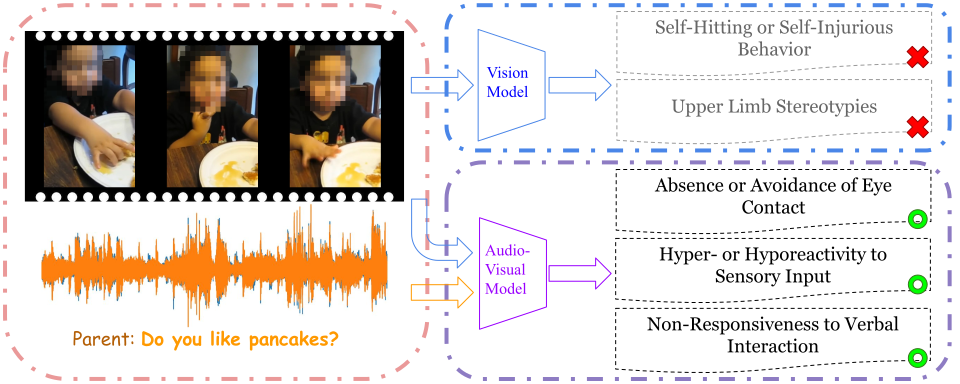
Combines video, audio, and speech to recognize autism-related social and repetitive behaviors.